Configure the automatic UTF-8 conversion feature
Overview
When the source code delivered to CAST Imaging contains characters whose encoding or character set is not UTF-8, this can cause problems during the analysis phase - see Supported character sets for the encodings that are supported and the impact of unsupported characters. CAST Imaging warns you that the source code contains non UTF-8 encoded characters and provides a list of the files impacted - see Overview - Run Analysis section:
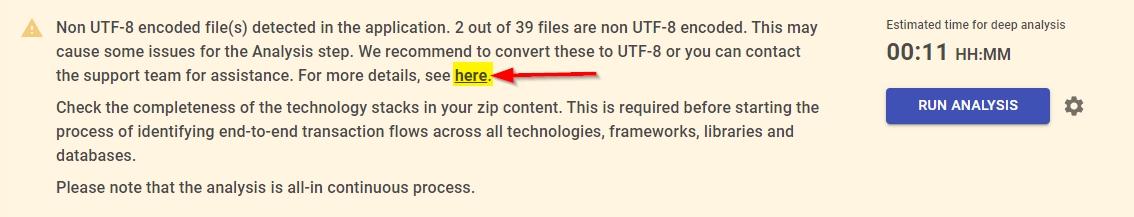
To reduce the number of warnings in the analysis log and improve the analysis results, CAST Imaging converts these files automatically to UTF-8 during the Content Discovery step of the fast scan. This feature is enabled “out-of-the-box”. If you need to disable it or modify any of the options, follow the instructions below.
Step 1 - Check the shipped configuration
The feature is configured in the application.sourceCodeFiles section of the following file, which is available on EACH analysis node:
Microsoft Windows

  %PROGRAMDATA%\CAST\Imaging\CAST-Imaging-Analysis-Node\application.yml

Linux via Docker/Podman/Kubernetes - located within the analysis-node container

  /home/carl/data_aip_node_v3/application.yml
To view the file in a Docker/Podman/Kubernetes deployment, enter the container in shell:
$ sudo docker exec -it analysis-node sh
Consult this file to see the shipped settings, but do not edit it - add your customizations to application-default.yml as described in Step 2.
The shipped settings are as follows:
application:
  ...
  sourceCodeFiles:
    # Character set that will be assumed for source files whose character set could
    # not be found: can be "JVM", standing for "the default Charset of this Java
    # virtual machine", or the name of any Charset supported by the current JVM.
    # Note: Character set names are case-insensitive.
    assumedEncoding: JVM
    conversionToUtf8:
      # Whether automatic conversion of non UTF-8 source code files
      # to UTF-8 is enabled during Onboarding with Fast Scan.
      enabled: true
      # Regular expression to match application names to perform UTF-8
      # conversion on (will match all applications if left empty).
      appNameFilter:
      # Option to enable backup before conversion.
      backupFiles: true
      # Types of paths to display in the conversion logs and reports.
      # Valid values: absolute, relative, or filename
      pathsInReports: absolute
      # Comma-separated list of file extensions, with no leading dot, to add to
      # those issued from the Application Scan, that will be converted to UTF-8
      # unless they are part of removed extension (set in fileExtensionsRemoved).
      fileExtensionsAdded:
      # Comma-separated list of file extensions, with no leading
      # dot, to ignore during the conversion of files to UTF-8.
      fileExtensionsRemoved: ani, avi, bin, bmp, bz2, chi, chm, class, com, csv, dib, dll, doc, docx, dump, exe, exp, frx, gif, gz, ico, idb, ilk, iml, ini, jar, jfif, jpe, jpeg, jpg, lib, log, mp3, mp4, msi, pbd, pdb, pch, pdf, png, ppt, pptx, rtf, sys, tar, tif, tiff, tgz, txt, vhdx, war, wav, webp, xls, xlsx, zip, xml, axml, ccxml, clixml, cproject, dita, ditamap, ditaval, glade, grxml, jelly, kml, mxml, plist, pluginspec, ps1xml, psc1, pt, rdf, rss, scxml, svg, tmCommand, tmLanguage, tmPreferences, tmSnippet, tmTheme, tml, ui, vxml, wxi, wxl, wxs, x3d, xaml, xlf, xliff, xmi, xul, zcml
      # Regular expression defining, if any, the names of character sets and
      # encodings for which source code files will not be converted to UTF-8.
      preservedEncodings: ".*UTF-(16|32).*|x-IBM930"
      # Whether to log the paths of files retained as candidates for conversion to UTF-8.
      logRetainedFiles: false
      # Whether to log the paths of files rejected as candidates for conversion to UTF-8.
      logRejectedFiles: false
      # Whether to log the paths of files that have actually been converted to UTF-8.
      logConvertedFiles: true
Step 2 - Add your customizations
Edit the following file in a text editor - this file is available on EACH analysis node, therefore if you have more than one node, you will need to make this change on all nodes where you want to configure the feature:
Microsoft Windows

  %PROGRAMDATA%\CAST\Imaging\CAST-Imaging-Analysis-Node\application-default.yml

Linux via Docker/Podman/Kubernetes - located within the analysis-node container

  /home/carl/data_aip_node_v3/application-default.yml
You should always add configuration to the application-default.yml for customization purposes since it overrides the content of application.yml and the file is never overwritten during an update of the Node.
In a Docker/Podman/Kubernetes deployment this file is located inside the analysis-node container and is not exposed to the host file system: any changes made directly inside the container will be lost when the container is updated or recreated.
Add an application.sourceCodeFiles section containing only the parameters you want to override - any parameter you do not list keeps its shipped value from application.yml. The parameters are described below:
| Item | Description |
|---|---|
application.sourceCodeFiles.assumedEncoding |
Character set that will be assumed for source files whose character set could not be found: can be JVM (default setting), standing for “the default Charset of this Java virtual machine”, or the name of any character set supported by the current JVM. Character set names are case-insensitive.If the character set name you enter is not recognized (i.e. incorrectly spelt or not a valid character set) then a warning will be recorded as follows:
|
application.sourceCodeFiles.conversionToUtf8.enabled |
Whether automatic conversion of non UTF-8 source code files to UTF-8 is enabled during the fast scan - the conversion is applied during the Content Discovery step. Set to true or false. |
application.sourceCodeFiles.conversionToUtf8.appNameFilter |
Regular expression defining, if any, the name(s) of the only applications whose non UTF-8 source files must be converted. No filtering occurs when this field is empty. Ensure that the regular expression is surrounded with double quotes ( ") to avoid issues because of characters having special meaning in a YAML file, such as + or # for instance. |
application.sourceCodeFiles.conversionToUtf8.backupFiles |
Whether source code files that will be converted to UTF-8 should be backed up before conversion. Set to true or false.If true, each file will be backed up in the same directory as the original file, with the same name but whose extension will be suffixed with .genuine@<date>-<time>(<encoding>) where <date>-<time> corresponds to the moment the fast scan / Content Discovery started (this date and time will be the same for all files), and <encoding> is the encoding or character set found (or assumed) for the file. For instance the backup of the non UTF-8 file main.java found to have been encoded in Shift_JIS will be named main.java.genuine@20230525-084129(Shift_JIS) if the fast scan / Content Discovery started on May 25th, 2023, at 08:41:29 AM.If over time several versions of the same files are delivered, their repeated conversion to UTF-8 will result in repeated creation of backup files since their filenames are timestamped. To avoid the accumulation of outdated backup files, once the conversion of all application files to UTF-8 has completed, only the most recent backup of each file that has again been converted to UTF-8 is kept. Once this process has ended, the following line is logged: [INFO] Old backup files (count = N) of '<application-name>' could be deleted in folder '<sources-root-path>' |
application.sourceCodeFiles.conversionToUtf8.pathsInReports |
Configures the type of paths that will be logged in reports about files of an application that have been considered for conversion to UTF-8, or that have not been considered because of filtering by file extension. Can be set to one of the following:
|
application.sourceCodeFiles.conversionToUtf8.logRetainedFiles |
Whether to log the paths of files retained as candidates for conversion to UTF-8 (due to their filename extension). Set to true or false. |
application.sourceCodeFiles.conversionToUtf8.logRejectedFiles |
Whether to log the paths of files rejected as candidates for conversion to UTF-8 (because of their filename extension). Set to true or false. |
application.sourceCodeFiles.conversionToUtf8.logConvertedFiles |
Whether to log the paths of files that have actually been converted to UTF-8. Set to true or false. |
application.sourceCodeFiles.conversionToUtf8.fileExtensionsAdded |
Comma-separated list of strings (there can be none - i.e. this is optional), with no leading dot, whose files with such extension will always be considered (in addition to the file extensions resulting from the application scan) for conversion to UTF-8 because files with these extensions are known to contain some source code. By default, this property will be empty. For example:fileExtensionsAdded: txt, java
|
application.sourceCodeFiles.conversionToUtf8.fileExtensionsRemoved |
Comma-separated list of strings (there can be none - i.e. this is optional), with no leading dot, whose files with such extension will never be considered for conversion to UTF-8 because such files are known not to be source code files, or they should not be converted to UTF-8. By default, this property contains the list of file extensions shown in Step 1. If you declare it in application-default.yml, the value you supply replaces the shipped list in full rather than adding to it, so copy the shipped list and edit it rather than listing only the extensions you want to add. For example:fileExtensionsRemoved: xls, xlsxThese file extensions will be removed not only from those resulting from the application scan, but also from the fileExtensionsAdded property (see above) if they also exist there - file extensions defined here have a higher precedence than those issued from the application scan process or defined by the fileExtensionsAdded property.
|
application.sourceCodeFiles.conversionToUtf8.preservedEncodings |
Regular expression defining (if there is one - i.e. this is optional) the names of character sets and encodings for which source code files (that have been found with the matched character set or encoding) will not be converted to UTF-8. For convenience, matching is done regardless of letter case. If this property is empty or disabled, no filtering will occur for a file because of the character set or encoding that was found or assumed for it. By default, this property contains the following regular expression, which ensures that any source code files found with either UTF-16 or UTF-32 will not be converted to UTF-8 (additional expressions can be added):preservedEncodings: ".*UTF-(16|32).*"The property value should be surrounded with double quotes ( ") to avoid issues because of characters having special meaning in YAML, such as + or #. |
Example - restrict the conversion to certain applications
The example below converts non UTF-8 source code files only where the name of the application they belong to contains “foo” (case-sensitively) or contains “bar” (case-insensitively), and sets the character set assumed for source code files whose character set could neither be found (for instance thanks to a BOM) nor guessed (by sampling followed by a validation of the guess against the entire file) to ISO-8859-1, corresponding to the Western European code page.
Only the two parameters being changed are listed - every other parameter keeps its shipped value, including preservedEncodings, which continues to exclude UTF-16 and UTF-32 files from the conversion:
application:
  sourceCodeFiles:
    assumedEncoding: ISO-8859-1
    conversionToUtf8:
      appNameFilter: ".+(foo|[bB][aA][rR]).+"
Example - disable the feature
application:
  sourceCodeFiles:
    conversionToUtf8:
      enabled: false
Save the file when you have completed the changes.
Step 3 - Apply configuration changes
Restart the analysis node to ensure all changes are taken into account. You may have more than one analysis node to restart.
Microsoft Windows
- Open Services (
services.msc) - Locate CAST Imaging Analysis Node
- Right-click and select Restart
- Repeat for each modified analysis node
Linux via Docker/Podman/Kubernetes
$ cd /opt/cast/installation/imaging-node    # navigate to installation folder
$ sudo docker compose down                  # stop the containers
$ sudo docker compose up -d                 # start the containers in detached mode
$ sudo docker ps                            # check containers are running